
← Monday, September 28, 2026InferenceDeep dive
Prompt-lookup drafting in llama.cpp gets up to 42× faster with less memory
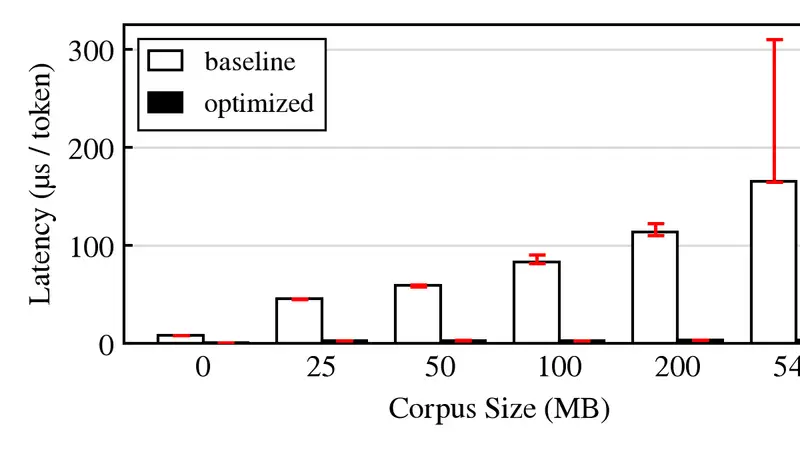
The author reports optimizations that make prompt-lookup drafting up to 42× faster while using up to 2.6× less memory; a follow-up contribution raises the reported speedup to 140×. These results make the implementation relevant to engineers tuning speculative decoding in inference engines.
- What
- Prompt lookup decoding drafts tokens from n-gram caches to accelerate generation in llama.cpp.
- How
- The optimizations make drafting up to 42× faster with up to 2.6× less memory; a later PR adds up to 4.2× on top.
- Why it matters
- Reducing drafting time and memory can improve inference efficiency in engines that support prompt lookup decoding.
Read on jadidbourbaki.github.io → Hacker News · 12 comments
Discussion
Discussion is not switched on yet. Use Note above to keep your own thoughts on this story.
Headline, summary, brief and diagram are written by a model from the source's own text; the link, byline and numbers come from the source. Read the original before relying on a claim.
