
← Wednesday, October 14, 2026Models & trainingDeep dive
EmbeddingGemma 2 transcribes an hour of audio in 12.6 seconds on a MacBook Air
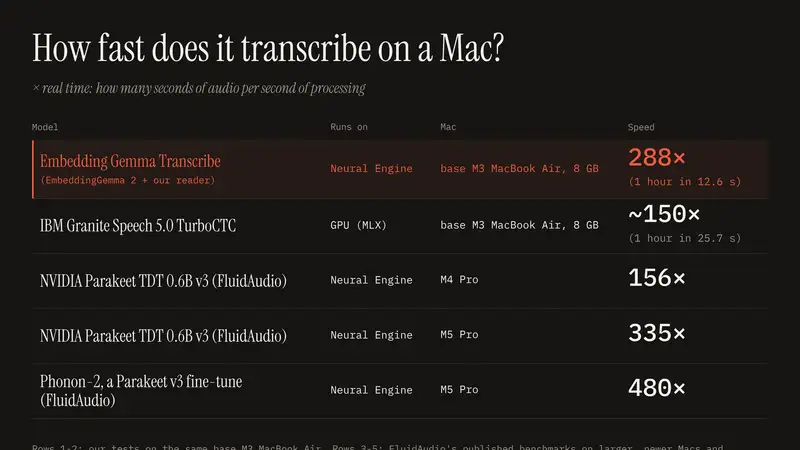
A small trained reader maps audio-encoder slices into a space of roughly 229,000 English words; the base embedding model stays unchanged, and an hour of audio takes 12.6 seconds on an M3 MacBook Air. This is a practical example of repurposing a multimodal model for fast, on-device speech recognition.
- What
- - EmbeddingGemma 2, an embedding model, was adapted to transcribe speech locally on a Mac.
- How
- - Its unchanged audio encoder feeds a small reader that maps audio slices into text space; the closest of about 229,000 English words is selected, then another model adds punctuation and capitals.
- Why it matters
- - The approach transcribes an hour of audio in 12.6 seconds on a base M3 MacBook Air and keeps audio on-device, though its word error rate is about 5% versus 2–3% for leading speech models.
Read on eg2.haku.sh → Hacker News · 89 comments
Discussion
Discussion is not switched on yet. Use Note above to keep your own thoughts on this story.
Headline, summary, brief and diagram are written by a model from the source's own text; the link, byline and numbers come from the source. Read the original before relying on a claim.
