· No. 3

Monday, September 28, 2026

The day in one minute

Today’s results put production-path validation and tradeoffs in focus. Coding-agent patches passed less often with live-serving checks; a GPU capacity test raised throughput but also increased P99 time to first token. Confidential inference retained most baseline throughput with added per-token latency, reinforcing that deployment gains need to be judged against their costs.

  1. SWE-Serve finds live-serving checks cut coding-agent pass rates to 45.9%
  2. DSX MaxLPS raises GPU throughput 49.2% within the same power budget
  3. Confidential inference retains up to 98.2% of baseline throughput on B200 GPUs
Collected
460
Scored
320
Kept
50
Sources
47
Today's pulseOne beat per story, in page order. Taller beats scored higher.

Models & training Paper

Chat templates shift LLMs between disclaimer and experiential voices

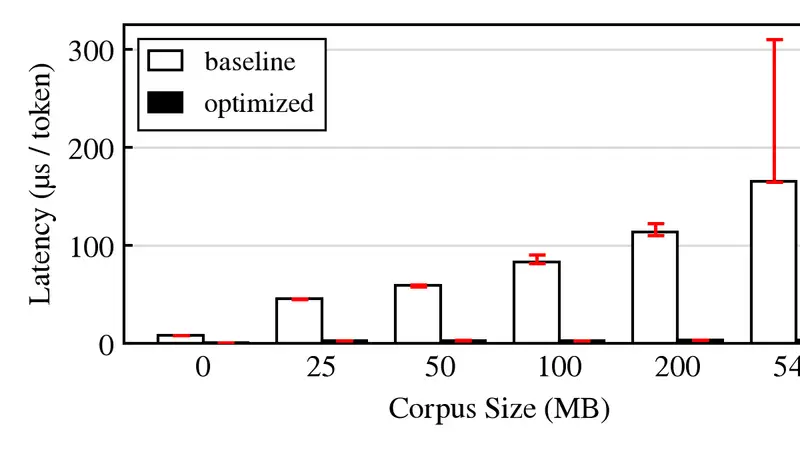
Across eight open-source models up to 9B parameters, the study finds that chat templates increase disclaimer-style self-reports, while removing them shifts responses toward experiential language. This suggests deployment formatting can confound conclusions drawn from model self-reports.

  • WhatChat templates shift LLM self-reports between disclaimer and experiential voices.
  • MethodAcross 8 open-source instruct models up to 9B parameters, templates raised disclaimer voice; activation steering reproduced the shift in 3 models.
  • Why it mattersTemplate-dependent self-descriptions can confound safety or introspection studies, so engineers should control prompt formatting.
Original · arxiv.org 3 min read HN 101 pts · 101 comments

Notes & discussion

Cloud & infra Tool

Fakecloud emulates 105 AWS services for local integration tests

Fakecloud says it supports 7,508 operations and passes all 248,557 Smithy variants, while letting applications use regular AWS clients locally. Realistic local integration tests can shorten feedback loops for teams building on AWS.

  • Whatfakecloud is a local AWS cloud emulator for integration tests, supporting 105 AWS services and normal AWS clients.
  • HowApps use AWS clients against localhost; fakecloud SDKs inspect effects, reset state, and control asynchronous processors.
  • Why it mattersLocal, service-connected behavior lets engineers test real application flows without stitching together mocks, polling, and private hooks.

Original · fakecloud.dev 5 min read HN 132 pts · 64 comments

Notes & discussion

Trending models Hugging Face

#ModelLikesMove
1 Edge0/Audio8-ASR-Infiniteautomatic speech recognition 1.3K+404 ▲ 2
2 XingChen-AGI/Xing4.0-29B-A4Btext generation 1.8K+54 ▼ 1
3 Altworld/Hemmingway-1text generation 746+32 ▲ 1
4 prism-ml/Ternary-Bonsai-2-27B-gguftext generation 2.2K+57 ▼ 2
5 XiaomiMiMo/MiMo-V2.6-Pro-RLtext generation 564+34 –

Fast-rising repositories GitHub, created this week

#RepositoryStarsMove
1 Contrastive-LM/CLM 2K+371 ▲ 2
2 tobi/disktree 1.7K+333 ▲ 2
3 mexicat/pdoom-video 1.4K New

Agents

9 stories Topic page →

Deep dive

TLA+ and proof tools offer a path to verifying agent-built software

The piece introduces TLA+ and connects temporal specifications, modern proof systems and AI agents in a workflow for modeling behavior and generating machine-checked proofs. Engineers using coding agents can apply formal methods to check system behavior, not just code output.

  • WhatTLA+ specifies allowed system behaviors and properties, but model checking checks finite models rather than implementations.
  • HowAn agentic pipeline converted 16,000+ TLA+ specification/property pairs into 3,000+ machine-checked Verus proofs.
  • Why it mattersLinking specifications, proofs, and implementations offers a path to verifying agent-built software beyond model checking alone.

Original · reasonable.io 10 min read HN 121 pts · 62 comments

Notes & discussion
2 more stories

Inference

7 stories Topic page →

Benchmark

DSX MaxLPS raises GPU throughput 49.2% within the same power budget

In an evaluation, DSX MaxLPS ran 192 GPUs instead of 140 within a 264.4 kW budget, raising aggregate throughput 49.2%; P99 time to first token rose 17%. The results show why capacity gains need to be weighed against tail latency.

  • WhatDSX MaxLPS dynamically allocates power across participating resources under policy controls.
  • HowOn GB300 NVL72 systems running Kimi K2.5, 192 GPUs raised normalized throughput 49.2% over a 140-GPU baseline at the same 264.4 kW.
  • Why it mattersP99 time to first token rose 17%, so operators must include tail latency when validating capacity gains.

Original · developer.nvidia.com by Sarah McKenney9 min read

Notes & discussion

Models & training

6 stories Topic page →

Paper

FuseReg improves image generation by training across encoder-layer subsets

FuseReg trains a decoder on random subsets of encoder layers; on ImageNet-256 it reportedly improves reconstruction flexibility and cuts unguided gFID by 27% through decoder replacement alone. The result suggests a practical way to separate representation choices from generator retraining.

  • WhatFuseReg trains decoders on random subsets of pretrained encoder layers rather than fixed layer fusions.
  • MethodOn ImageNet-256 with DINOv3-L, one decoder handles full, sparse, and single-layer fusions without retraining and achieves higher PSNR than fixed-fusion decoders.
  • Why it mattersDecoder replacement alone reduced unguided gFID by 27% with the RAEv2 DiT-XL generator unchanged.

Original · huggingface.co by Hongyang Du et al.67 upvotes Code · 2 stars

Notes & discussion

Architecture

4 stories Topic page →

Deep dive

S3’s request-level limits challenge the stateless-compute architecture

The piece argues that S3’s hardware assumptions shape data-system architectures, noting that individual requests deliver less than 100 MB/s while large parallel workloads can achieve high aggregate bandwidth. Engineers building data-intensive systems should consider how object-store limits affect architecture.

  • WhatS3-based systems pair object storage with mostly stateless compute, relying on caching, batching, and separate metadata stores to work around request limits.
  • HowThe excerpt argues SSD-based disaggregated storage and datacenter networking could enable microsecond access, small random I/O, and in-place updates.
  • Why it mattersEngineers choosing storage architectures must weigh S3's durability and low capacity cost against latency and request-level overheads.

Original · btrblocks.com 3 min read HN 62 pts · 85 comments

Notes & discussion
access object access lookups statelesscompute caching layers metadata store S3
The diagram shows stateless compute using S3, caching layers, and a separate metadata store. Sketched from the article's own text.

Performance & OS

4 stories Topic page →

Deep dive

A FLIP fluid simulation runs on a noisy electromechanical flip-dot display

The project puts a FLIP fluid simulation on a flip-dot display, with a detailed account of the panels, circuit boards, power system, and controls. It’s a substantial hands-on build spanning simulation and hardware, though it’s a one-off installation.

  • WhatA FLIP fluid simulation was put on an electromechanical flip-dot display for an EMF2026 installation.
  • HowEach dot uses permanent magnets and polarizable cores to set its state, and retains that state without power.
  • Why it mattersThe project uses the display’s mechanical motion to pursue audible fluid movement, unlike the author’s otherwise-silent LED simulations.

Original · mitxela.com 52 min read HN 376 pts · 24 comments

Notes & discussion

Cloud & infra

6 stories Topic page →

Guide

Tor hidden services expose a site without DNS or a public IP

A hidden service routes traffic to a local port using a Tor-owned directory, without DNS, a certificate authority or an exposed IP. The setup is a useful, compact example of privacy-focused network hosting.

  • WhatA Tor hidden service makes a site reachable at an onion address without DNS, a certificate authority, or an exposed server IP.
  • HowTor forwards the hidden service’s port 80 to a local port where nginx listens; Tor provides the connection’s encryption.
  • Why it mattersThis setup lets engineers self-host a site over Tor while keeping the server’s public IP undisclosed.

Original · david.alvarezrosa.com HN 141 pts · 50 comments

Notes & discussion
Tor traffic port 80 → 8080 Tor relays hidden service nginx
Tor traffic reaches the hidden service, which forwards requests to nginx on a local port. Sketched from the article's own text.

Databases

2 stories Topic page →

Deep dive

DuckDB queries Hugging Face datasets directly over `hf://`

DuckDB can query CSV, JSONL, and Parquet files in Hugging Face dataset repositories through `hf://` without downloading them first. This can simplify exploratory analysis and access to ML datasets without a separate warehouse.

  • WhatDuckDB can query Hugging Face dataset files directly through the hf:// protocol, without first downloading them.
  • HowThe hf:// scheme builds on httpfs to resolve dataset repositories to files, and DuckDB reads only the columns a query needs.
  • Why it mattersFor AI data workflows, querying remote datasets in place avoids a separate copy before analysis.

Original · duckdb.org by The DuckDB team6 min read

Notes & discussion
queries path uses reads files DuckDB hf:// protocol httpfs extension Hugging Face Hub
DuckDB uses the hf:// path scheme and httpfs to read dataset files hosted on Hugging Face Hub. Sketched from the article's own text.

Security

1 story Topic page →

Postmortem

LuaRocks.org RCE was exploited, prompting a full credential reset

After finding that an RCE had been exploited, LuaRocks rebuilt its server and revoked credentials, sessions, and exposed secrets. The incident is a useful reminder of the blast radius of compromise at a software package service.

  • WhatLuaRocks.org disclosed that attackers exploited a remote-code-execution vulnerability and reset credentials held by the old server.
  • HowLuaJIT accepted precompiled bytecode as a rockspec; crafted bytecode could escape the intended sandbox and access server memory.
  • Why it mattersFor package-system engineers, the incident shows why untrusted metadata must reject bytecode and why server compromise calls for broad credential rotation.

Original · luarocks.org 5 min read Lobsters 29 pts · 5 comments

Notes & discussion

Languages & tools

5 stories Topic page →

Guide

Custom domains keep Go import paths independent of Git hosting

Using a custom domain for Go imports can decouple package paths from a hosting provider, avoiding import changes when moving repositories. That makes dependency ownership and future migrations easier to manage.

  • WhatCustom domains let Go import paths remain stable when a project changes Git hosting providers.
  • HowA Go tool queries the domain for go-import metadata, which points it to the repository; human visitors can be redirected separately.
  • Why it mattersStable import paths reduce migration work and avoid coupling internal libraries to a hosting provider.

Original · iain.rocks HN 216 pts · 99 comments Lobsters 22 pts · 8 comments

Notes & discussion
go-get query serve metadata repository lo… fetch code Go tool go.iain.rocks index.html GitHub
The Go tool discovers repository metadata at a custom domain before fetching code from GitHub. Sketched from the article's own text.

Web

1 story Topic page →

Tool

A cross-platform Markdown editor keeps notes as plain files

The editor renders Markdown in place, stores notes as plain files, keeps version history, and syncs shared notes peer to peer over WebRTC. Its custom contenteditable implementation and cross-platform constraints offer useful product-engineering detail.

  • WhatBeauty is a Markdown editor for Mac, iPhone, and web, with notes stored as plain .md files on Mac.
  • HowIt renders Markdown in place, supports tables, KaTeX math, and Mermaid diagrams, and keeps 200 versions per note.
  • Why it mattersPlain-file storage preserves interoperability, while a custom contenteditable editor avoids browser document restructuring.

Original · markdown.beauty HN 65 pts · 49 comments

Notes & discussion

Practice & careers

1 story Topic page →

Paper

Google study links perceived code quality to developer productivity

A study of Google developers across 39 productivity factors finds that increases in perceived code quality tend to precede increases in self-reported productivity. The findings inform engineering investment decisions, though the outcome measures are self-reported.

  • WhatA Google study examined how technical and organizational factors relate to developers’ self-reported productivity.
  • MethodIts lagged panel analysis found that increases in perceived code quality tend to precede increased perceived productivity, but not vice versa.
  • Why it mattersFor engineering organizations, the findings make code quality a potential productivity investment, alongside tools, technical debt, communication, and priorities.

Original · dl.acm.org Lobsters 17 pts · 1 comment

Notes & discussion

Sources today: AWS Machine Learning, ByteByteGo, Cloudflare Blog, Google DeepMind, Discord Engineering, DuckDB, Figma Engineering, Google Cloud, GitHub Engineering, Go Blog, Google Research, Hugging Face, Import AI, InfoQ, Interconnects, Julia Evans, Kubernetes, Latent Space, Lobsters (AI, distributed, performance), LWN.net, Martin Fowler, Engineering at Meta, Microsoft Research, Metadata (Murat Demirbas), Netflix TechBlog, NVIDIA Technical Blog, The Old New Thing, OpenAI, Pinterest Engineering, PlanetScale, Postgres Weekly, The Pragmatic Engineer, PyTorch, Rust Blog, Shopify Engineering, Simon Willison, Stripe Engineering, Trail of Bits, WebKit, GitHub (new repositories), Hugging Face trending models, Hugging Face Daily Papers, Hacker News, Hacker News (AI and systems search), Lobsters, Ollama releases, vLLM releases. Headlines, summaries and diagrams are written by gpt-6-luna from each source's own text; links and images come from the sources themselves. Follow the link before relying on a claim.

RSS · JSON · Markdown · Pulse · Search · Previous days

Your note

Private to you. Stored in this browser, and synced to your account when you are signed in.